+ Document & Voice AI · Flagship
Document Intelligence Pipeline
Turns invoices, receipts and scans into validated JSON: OCR, schema-constrained LLM extraction, arithmetic checks with a repair loop, per-field confidence and review flags.
99.6%field-level accuracy on 250 fields
Overview
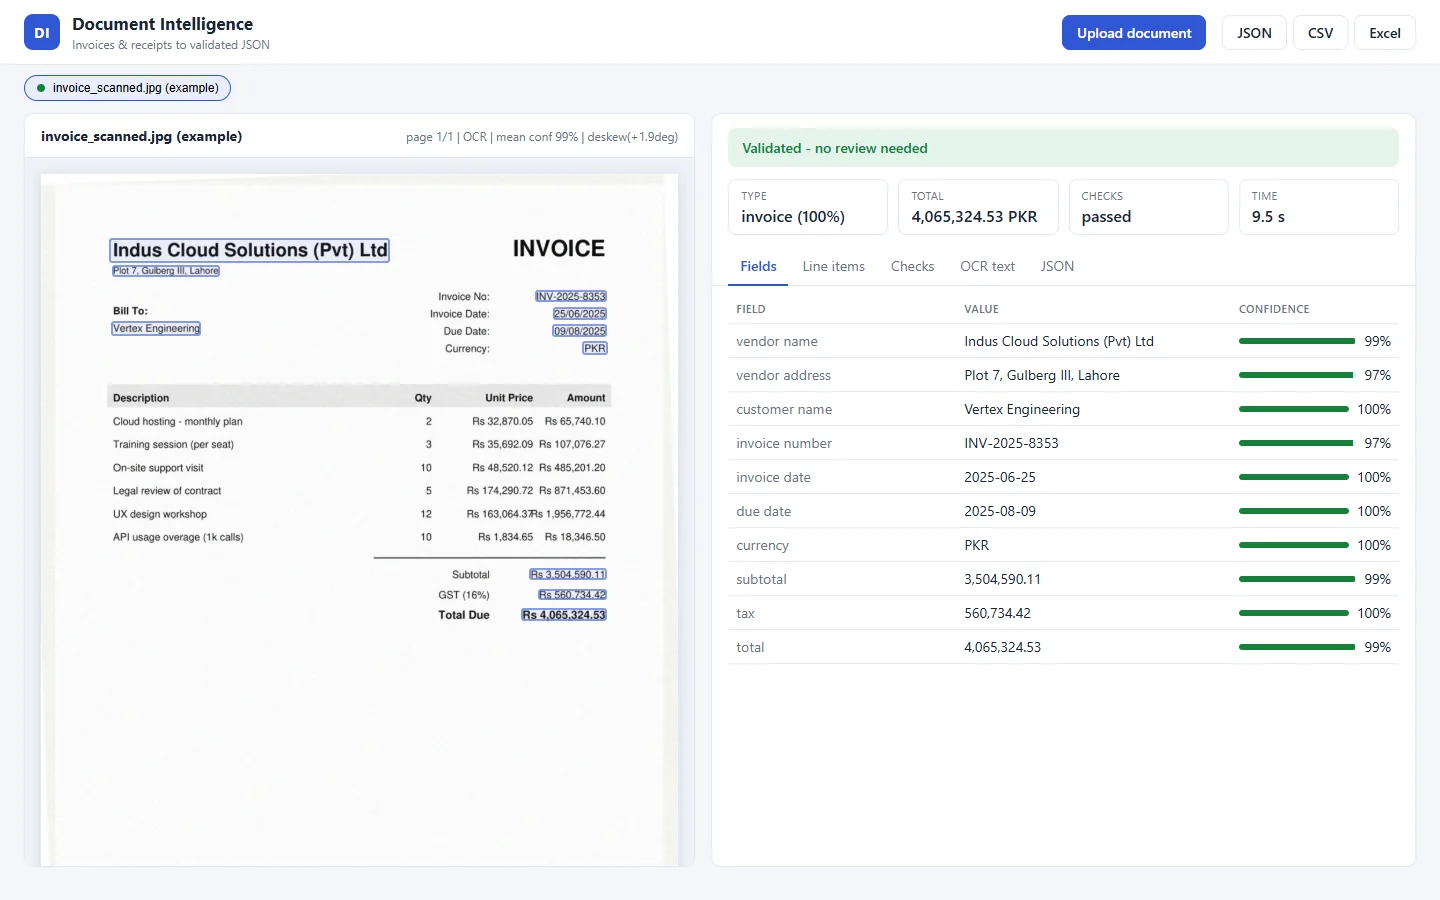
A CPU-only pipeline that reads PDFs (text layer or OCR fallback) and images, cleans scans with OpenCV, and extracts invoices and receipts into strict Pydantic schemas with an LLM. Output is checked against the document's own arithmetic and dates; failures are sent back to the model with the exact error, and documents that still fail are flagged for human review. Every field is traced to its OCR line for a confidence score and bounding box. Ships as a batch CLI, a FastAPI service and a review UI.
Highlights
- 99.6% field-level exact-match accuracy on 250 fields (28 synthetic documents), 99.2% on scanned/noisy variants
- 100% document-type classification on the evaluation set
- Validate-and-repair loop driven by schema and business-rule errors (line totals, subtotal + tax = total, dates)
- Per-field confidence and bounding boxes traced back to OCR lines, with human-review flags
- CLI, REST API and web UI with JSON/CSV/Excel export; 81 offline tests