+ GenAI & RAG · Flagship
Enterprise RAG Assistant
Production-style RAG service: hybrid BM25 + dense retrieval, RRF fusion and cross-encoder reranking, with grounded, cited answers, SSE streaming and a measured evaluation harness.
0.977Hit@1 with hybrid search + reranking
Overview
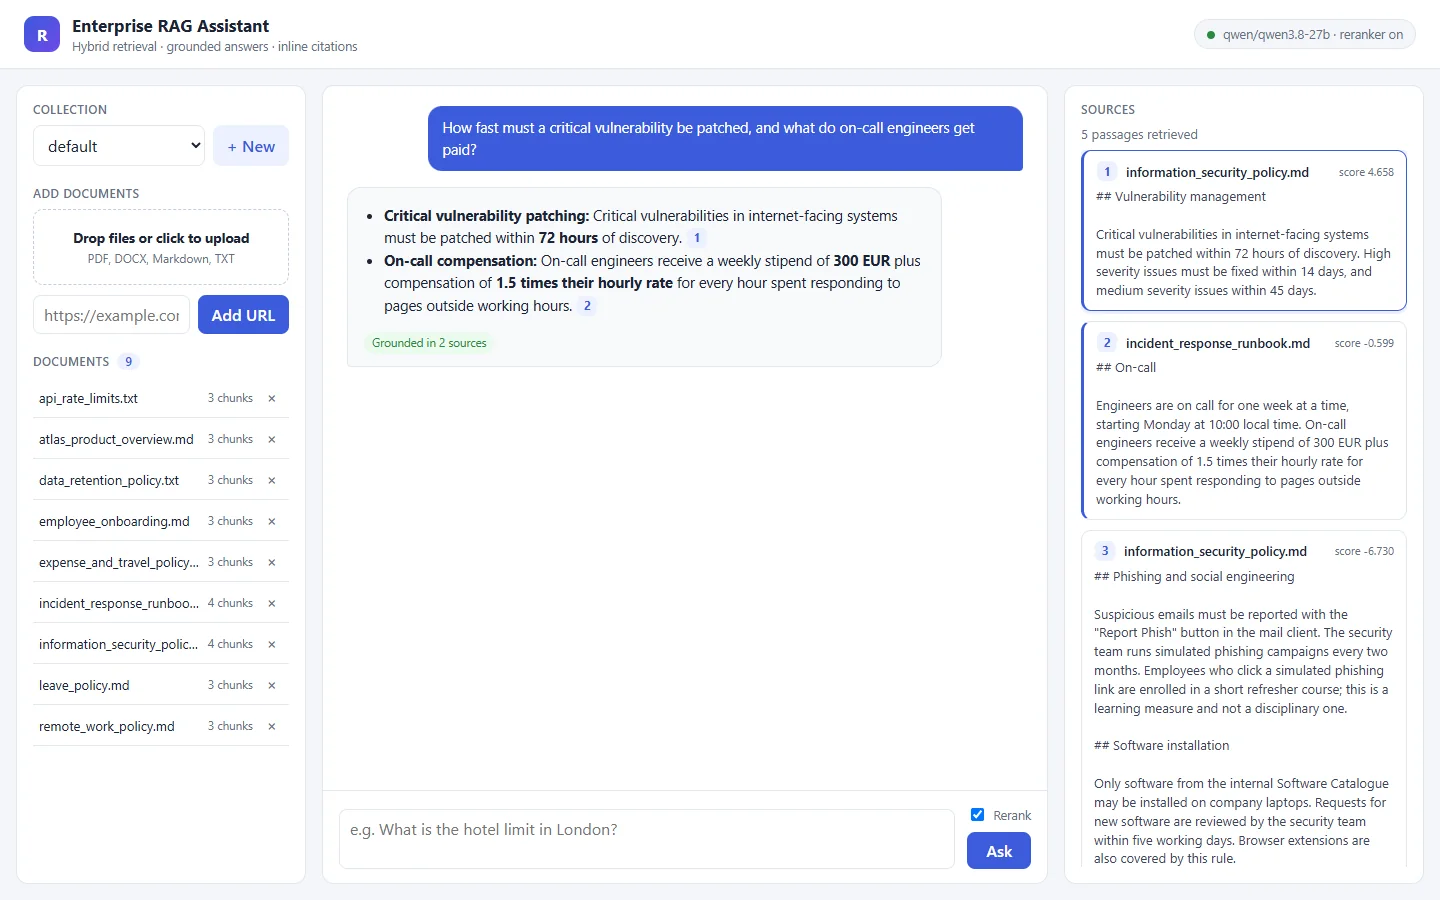
A Retrieval-Augmented Generation service that ingests PDF, DOCX, Markdown, TXT and web pages and answers questions with inline citations mapped to source and page. Retrieval fuses BM25 and dense embeddings (fastembed + Qdrant) with Reciprocal Rank Fusion, then reranks with a cross-encoder, all on CPU through ONNX. A strict grounding prompt and an explicit "I don't know" path keep answers faithful. It ships with a FastAPI backend with SSE streaming, a single-page UI, tests, CI, Docker and a reproducible retrieval and LLM-judge benchmark.
Highlights
- Hybrid retrieval + reranking raised Hit@1 from 0.86 (BM25) and 0.81 (dense) to 0.977, MRR@10 0.988, on a 43-question benchmark
- LLM-judged evaluation: 15/15 answers faithful and correct, 5/5 correct refusals on unanswerable questions
- Runs fully on CPU with ONNX models; hybrid retrieval about 30 ms median on a 2-core laptop
- Streaming SSE API and web UI with clickable citations to source file and page
- 59 offline tests, content-hash de-duplication, per-collection isolation and an SSRF guard on URL ingestion